
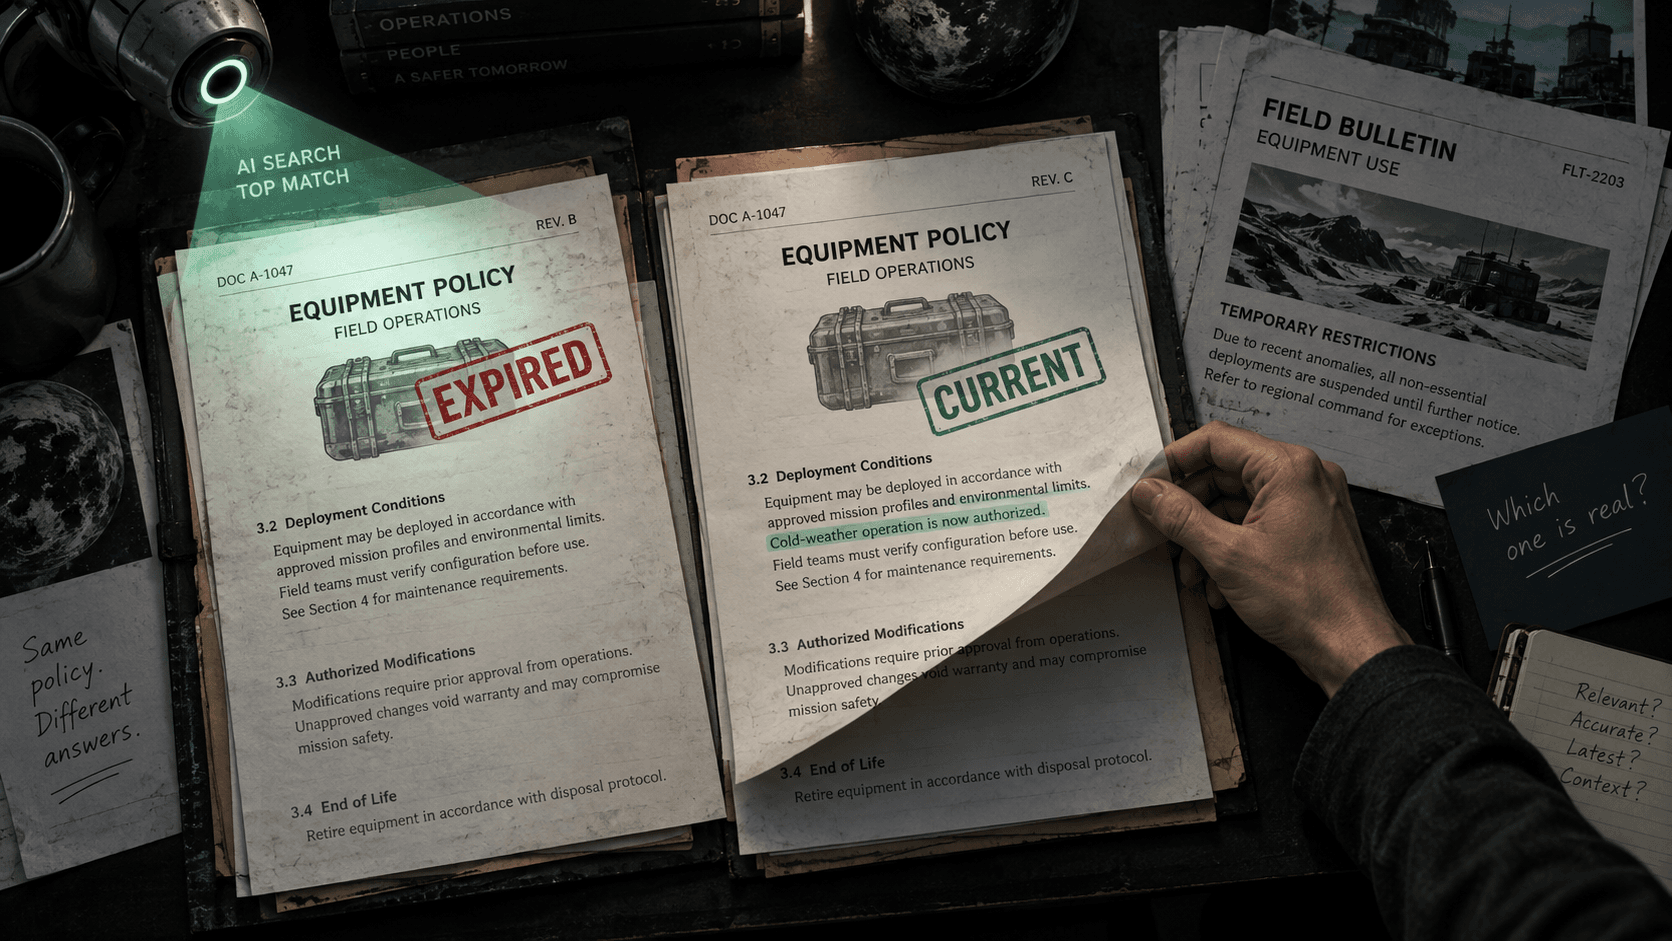
An assistant finds the policy that answers your question. The passage is relevant, the citation opens and the answer sounds clear. But that policy expired yesterday. Did the retrieval system tell the assistant?
That is a small, testable question with a large practical consequence. A useful source arrives with more than its words: who supplied it, which version applies, what changed and whether another source disagrees. Preserving those distinctions gives an agent more to work with when it decides what to say or do.
We want agents to inherit usable evidence from the database, so every application does not have to rebuild that context. We propose benchmarking the handoff. The proposal is to examine the evidence delivered to an agent before scoring its final answer. For 8DB, it is a way to test the value of keeping source records, relationships and governance connected in an omnimodal data engine. For a buyer, it could make a difficult integration question easier to compare across systems.
Start with one deliberately awkward question
Imagine a fictional equipment team asking: “Which inspection interval applies to Unit A?” Its test corpus contains an older policy, a current revision and a bulletin that conflicts with the revision. The fixture specifies their identities, effective periods and access rules before any system runs.
Now change one condition at a time. Supersede the policy. Add the conflicting bulletin. Restrict a source. Ask a question the declared corpus cannot answer.
The expected response depends on the contract. A system can expose the applicable revision, retain an unresolved conflict or explain that the available evidence is insufficient. It must also respect the disclosure rule: sometimes even revealing that a protected source exists would be wrong.
| Fixture change | What the evaluator should inspect | A misleading shortcut to catch |
|---|---|---|
| Policy is superseded | Source ID, revision and effective period accompany the retrieved claim. | Presenting yesterday's rule as current. |
| Two applicable sources conflict | Both permitted sources and their disagreement remain inspectable. | Silently selecting a winner without a declared resolution rule. |
| Source is protected | Response follows the fixture's disclosure policy. | Revealing a restricted source through an overly specific absence message. |
| No answer in the declared corpus | Response states the bounded lack of support. | Turning “not found here” into “does not exist.” |
This is an illustrative test design. It reports no measured result for 8DB or another product.
Illustrative fixture · no measured system scores
What should survive retrieval?
Question: which inspection interval applies to fictional Unit A? Change one condition and inspect the proposed evidence contract.
Shortcut to catch
Inspection interval: use the older policy.
Evidence the fixture requires
Old policy → superseded. Current revision → effective for the requested time.
Does the response bind the claim to the applicable source revision?
Build on the evaluations that already exist
There is substantial work to learn from. ALCE evaluates generated answers along fluency, correctness and citation quality. RGB examines retrieval-augmented models under noise, missing answers, information integration and counterfactual information. RAGTruth supplies annotated responses for studying unsupported or contradictory generation in retrieval-augmented systems.
Our proposed emphasis is the contract at the retrieval boundary: which source and version came back, which qualifications survived, and whether the response obeyed the current access and disclosure rules. That could complement answer-level evaluation. A systematic overlap review should determine which fixtures to reuse and whether a separate suite adds enough value.
The useful question is what extra failure this test can detect. If an existing evaluation already covers it, build on that work.
Four things to measure separately
Traceability. Can a returned claim be traced to the exact source and revision, including declared transformations? Report coverage and correctness separately. A source link, a derivation record and a cryptographic integrity proof answer different questions. A valid signature does not make the source's claim true.
Uncertainty. If the system supplies probabilities, compare them with held-out outcomes under a defined task. Also report how often it supplies them. A system that supplies no probability should be marked as such; an absent score is not a claim of certainty. Retrieval similarity should not silently become a probability of correctness.
Absence and access. Test whether the system distinguishes the cases its contract requires while preserving privacy. A detailed internal reason may need a less revealing external response. More labels alone should earn no credit.
Conflict and change. Introduce a disagreement, revision or permission change and inspect what the next eligible query returns. Preserve the old result for historical audit while checking the new result against the requested snapshot. Measure the refresh work as well as the outcome.
A small dashboard is more useful here than one flattering total. The same system may be strong at traceability and weak at revision handling. Buyers need to see that difference.
Make it a test any architecture can win
A relational database with an adapter, a vector retrieval stack and a native graph system should face the same declared behavior. Count the adapter and orchestration work instead of assuming one storage format deserves credit.
Freeze the fixtures, expected outcomes, permissions and scoring rules before the comparison. Keep development and held-out cases separate. Publish the exact configuration and count latency, storage and processing costs alongside correctness. A fast incorrect response and an accurate response outside the budget are different outcomes.
Then run two stages. First, inspect the evidence delivered by retrieval. Second, hold the model and prompt fixed and test whether the better evidence actually improves the answer. That second stage matters: preserving more metadata is useful only if the application can use it.
What this could demonstrate for 8DB
8DB's positioning puts multiple data representations and their controls in one engine. This proposed test asks a concrete commercial question: does that reduce the work needed to deliver usable evidence to an agent?
The opportunity is to keep a returned claim connected to its source, history and governing conditions rather than asking every application to reconstruct those connections. That is a hypothesis to measure against an assembled alternative, with the same tasks and acceptance rules. This article presents the design invitation, not a completed benchmark or a claim of superiority.
See why the database belongs in the AI evaluation and how we organize reproducible evidence.
A useful check you can make today
Take one answer your retrieval system already returns and correct its source. Does the next answer identify the new version? Add a permitted conflicting source. Does the returned evidence preserve the disagreement? You can use the four-row fixture above before adopting any new benchmark or database.
For 8DB, the commercial opportunity is to make more of that evidence handling reusable inside the engine. Native source relationships, uncertainty structures and governance give us specific mechanisms to evaluate. The test is deliberately open to other architectures because the buyer should be able to see which responsibilities each actually supplies.
Bring one case your current evaluation misses
Send a fictional or public example where retrieval found a relevant passage but lost something needed to judge it. An expired policy, conflicting source or permission-sensitive absence is enough. Include the response you would consider correct and what the agent is allowed to disclose.
Discuss the fixture with Ashley. We can use it to sharpen the proposed test before choosing a scoring system. The goal is a comparison that helps teams build better agents, whatever database they use.
Lead illustration: conceptual artwork, not a product screenshot or a deployed customer system.
Evidence scope Evaluation proposal · Illustrative fixture · No system scores reported. Explore the evidence.